Memo

共 49 条灌水 · 4

ArchLinux 编译 python-kornia-rs

安装 python-kornia-rs 失败,构建的时候 g 了。

直接一把梭搞定。

user@host [23:50:58] [~/.cache/yay/python-kornia-rs] [master *]
-> % makepkg -s
==> Making package: python-kornia-rs 0.1.9-5 (Thu 24 Jul 2025 11:51:05 PM CST)
==> Checking runtime dependencies...
==> Checking buildtime dependencies...
==> Retrieving sources...
  -> Found kornia-rs-0.1.9.tar.gz
==> Validating source files with sha256sums...
    kornia-rs-0.1.9.tar.gz ... Passed
==> Extracting sources...
  -> Extracting kornia-rs-0.1.9.tar.gz with bsdtar
==> Removing existing $pkgdir/ directory...
==> Starting build()...
* Getting build dependencies for wheel...
* Building wheel...
Running `maturin pep517 build-wheel -i /usr/bin/python --compatibility off`
🔗 Found pyo3 bindings
💥 maturin failed
  Caused by: Python interpreter should be a kind of interpreter (e.g. 'python3.8' or 'pypy3.9') when cross-compiling, got path to interpreter: /usr/bin/python
Error: command ['maturin', 'pep517', 'build-wheel', '-i', '/usr/bin/python', '--compatibility', 'off'] returned non-zero exit status 1

ERROR Backend subprocess exited when trying to invoke build_wheel
==> ERROR: A failure occurred in build().
    Aborting...
export PYO3_CROSS_PYTHON_VERSION=3.13
export PYO3_CROSS_LIB_DIR=/usr/lib
export CARGO_BUILD_TARGET=x86_64-unknown-linux-gnu
makepkg -sf

-> % ls -lah
total 2.8M
drwxr-xr-x 1 user user  310 Jul 24 23:53 .
drwxr-xr-x 1 user user  358 Jul 24 23:17 ..
drwxr-xr-x 1 user user  140 Jul 24 23:49 .git
-rw-r--r-- 1 user user 235K Jul 24 23:17 kornia-rs-0.1.9.tar.gz
-rw-r--r-- 1 user user   96 Jul 24 23:17 .nvchecker.toml
drwxr-xr-x 1 user user   76 Jul 24 23:53 pkg
-rw-r--r-- 1 user user 1.1K Jul 24 23:52 PKGBUILD
-rw-r--r-- 1 user user 2.3M Jul 24 23:53 python-kornia-rs-0.1.9-5-x86_64.pkg.tar.zst
-rw-r--r-- 1 user user 252K Jul 24 23:53 python-kornia-rs-debug-0.1.9-5-x86_64.pkg.tar.zst
drwxr-xr-x 1 user user   74 Jul 24 23:52 src
-rw-r--r-- 1 user user  793 Jul 24 23:17 .SRCINFO

-> % sudo pacman -U python-kornia-rs-0.1.9-5-x86_64.pkg.tar.zst
关闭 macOS 监听的端口 5000

我很喜欢 sigoden/dufs 这个项目,启动一个 HTTP server 还是共享文件,都非常方便。

但是 macOS 下会有一个烦人的家伙占用 5000 端口。

-> % dufs
Error: Failed to bind `0.0.0.0:5000`

Caused by:
    Address already in use (os error 48)

抓一下。

-> % sudo lsof -i -P | grep ":5000"
ControlCe   629        fanyang   12u  IPv4 0xdc924348e03ccb2f      0t0    TCP *:5000 (LISTEN)
ControlCe   629        fanyang   13u  IPv6 0xcb88b5ec8a71ad1a      0t0    TCP *:5000 (LISTEN)

好家伙,原来是 Control Center。这就把你干了。

Why always something is running at port 5000 on my mac

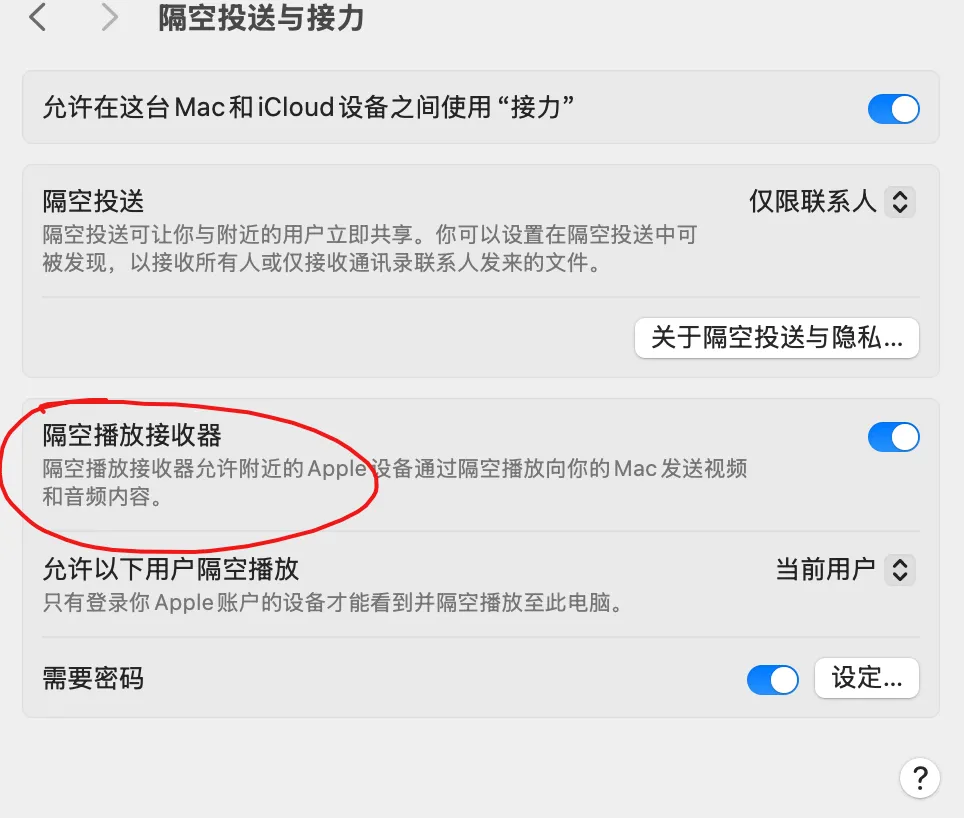
For fixing this you need to turn off System Settings > General > AirDrop & Handoff > AirPlay Receiver.

image.png

嗯,确实没了,很好。

把 ArchLinux 当成无线路由器用

刚进货一台新服务器,有两个有线网口,只有四个 PCIe,插一个无线网卡太浪费。那么就让他走到另一台有无线网卡的机器上网吧!

sudo pacman -S nftables
-> % cat /etc/nftables.conf
#!/usr/bin/nft -f
# vim:set ts=2 sw=2 et:

# IPv4/IPv6 Simple & Safe firewall ruleset.
# More examples in /usr/share/nftables/ and /usr/share/doc/nftables/examples/.

destroy table inet filter
table inet filter {
  chain input {
    type filter hook input priority 0; policy drop;

    ct state invalid drop comment "early drop of invalid connections"
    ct state {established, related} accept comment "allow tracked connections"
    iif lo accept comment "allow from loopback"
    ip protocol icmp accept comment "allow icmp"
    meta l4proto ipv6-icmp accept comment "allow icmp v6"
    tcp dport ssh accept comment "allow sshd"
    pkttype host limit rate 5/second counter reject with icmpx type admin-prohibited
    counter
  }

  chain forward {
    type filter hook forward priority 0; policy drop;
    iifname "enp2s0" oifname "wlo1" accept
    ct state established,related accept
  }

  chain output {
        type filter hook output priority 0; policy accept;
  }
}

table ip nat {
    chain prerouting {
        type nat hook prerouting priority 0; policy accept;
    }

    chain postrouting {
        type nat hook postrouting priority 100; policy accept;
        oifname "wlo1" masquerade
    }
}
-> % sudo systemctl enable --now nftables.service
-> % cat /etc/sysctl.d/30-ipforward.conf
net.ipv4.ip_forward=1

-> % sudo sysctl --system

ESXi GPU PCIe 直通后虚拟机无法启动

新到货一块 5080,在 ESXi 上配置 PCIe 直通后,并且在虚拟机上添加设备,虚拟机无法启动。

错误信息:模块“DevicePowerOn”打开电源失败。无法启动虚拟机。

PowerEdge:在 vSphere 上将 GPU 与虚拟机配合使用时,PCI 直通出现“Module 'DevicePowerOn' Power on failed”(模块'DevicePowerOn'开机失败)

满足上述要求后,必须将两个条目添加到虚拟机的 VMX 文件中,您可以直接修改该文件,也可以使用 vSphere Client 来添加这些功能,两种方法均能实现目标。第一个条目是:

pciPassthru.use64bitMMIO="TRUE"

指定第二个条目需要简单的计算。将想要传递到虚拟机的所有 GPU 设备 (*) 的 GPU 内存大小相加,然后四舍五入到下一个 2 的次幂。例如,要在具有 4 个 16 GB A2 设备的情况下使用直通,该值将为:32 + 32 = 64,四舍五入到下一个 2 的次幂,结果为 128。在第二个条目中使用此值:

pciPassthru.64bitMMIOSizeGB="128"

对 VMX 文件进行这两项更改后,请按照 VMware 知识库1010789标准 vSphere 说明此超链接会将您带往 Dell Technologies 之外的网站。,在主机级别启用直通设备并指定哪些设备应传递到虚拟机。在您的设备处于直通模式的情况下,虚拟机现在应该可以正常启动。

docker-compose.yml 合集

本篇文章收录了鄙人使用的各种服务的 docker-compose.yml

Milvus

services:
  etcd:
    container_name: milvus-etcd
    image: registry.example.com/quay.io/coreos/etcd:v3.5.18
    environment:
      - ETCD_AUTO_COMPACTION_MODE=revision
      - ETCD_AUTO_COMPACTION_RETENTION=1000
      - ETCD_QUOTA_BACKEND_BYTES=4294967296
      - ETCD_SNAPSHOT_COUNT=50000
    volumes:
      - ${DOCKER_VOLUME_DIRECTORY:-.}/volumes/etcd:/etcd
    command: etcd -advertise-client-urls=http://etcd:2379 -listen-client-urls http://0.0.0.0:2379 --data-dir /etcd
    healthcheck:
      test: ["CMD", "etcdctl", "endpoint", "health"]
      interval: 30s
      timeout: 20s
      retries: 3

  minio:
    container_name: milvus-minio
    image: registry.example.com/minio/minio:RELEASE.2023-03-20T20-16-18Z
    environment:
      MINIO_ACCESS_KEY: minioadmin
      MINIO_SECRET_KEY: minioadmin
    ports:
      - "9001:9001"
      - "9000:9000"
    volumes:
      - ${DOCKER_VOLUME_DIRECTORY:-.}/volumes/minio:/minio_data
    command: minio server /minio_data --console-address ":9001"
    healthcheck:
      test: ["CMD", "curl", "-f", "http://localhost:9000/minio/health/live"]
      interval: 30s
      timeout: 20s
      retries: 3

  standalone:
    container_name: milvus-standalone
    image: registry.example.com/milvusdb/milvus:v2.5.12
    command: ["milvus", "run", "standalone"]
    security_opt:
    - seccomp:unconfined
    environment:
      ETCD_ENDPOINTS: etcd:2379
      MINIO_ADDRESS: minio:9000
    volumes:
      - ${DOCKER_VOLUME_DIRECTORY:-.}/volumes/milvus:/var/lib/milvus
    healthcheck:
      test: ["CMD", "curl", "-f", "http://localhost:9091/healthz"]
      interval: 30s
      start_period: 90s
      timeout: 20s
      retries: 3
    ports:
      - "19530:19530"
      - "9091:9091"
    depends_on:
      - "etcd"
      - "minio"

networks:
  default:
    name: milvus

解决 PostgreSQL `could not open shared memory segment` 错误

解决 PostgreSQL could not open shared memory segment 错误。

打开 journalctl -u postgresql.service 可以看到:

Jun 15 11:55:52 fanyang-legion postgres[322924]: 2025-06-15 11:55:52.856 CST [322924] ERROR:  could not open shared memory segment "/PostgreSQL.2816709408": No such file or directory
Jun 15 11:56:52 fanyang-legion postgres[322973]: 2025-06-15 11:56:52.914 CST [322973] ERROR:  could not open shared memory segment "/PostgreSQL.2816709408": No such file or directory
Jun 15 11:57:52 fanyang-legion postgres[323026]: 2025-06-15 11:57:52.975 CST [323026] ERROR:  could not open shared memory segment "/PostgreSQL.2816709408": No such file or directory
Jun 15 11:58:53 fanyang-legion postgres[323076]: 2025-06-15 11:58:53.034 CST [323076] ERROR:  could not open shared memory segment "/PostgreSQL.2816709408": No such file or directory
Jun 15 11:59:53 fanyang-legion postgres[323127]: 2025-06-15 11:59:53.042 CST [323127] ERROR:  could not open shared memory segment "/PostgreSQL.2816709408": No such file or directory
Jun 15 12:00:53 fanyang-legion postgres[323181]: 2025-06-15 12:00:53.099 CST [323181] ERROR:  could not open shared memory segment "/PostgreSQL.2816709408": No such file or directory
Jun 15 12:01:53 fanyang-legion postgres[323229]: 2025-06-15 12:01:53.155 CST [323229] ERROR:  could not open shared memory segment "/PostgreSQL.2816709408": No such file or directory
Jun 15 12:02:53 fanyang-legion postgres[323286]: 2025-06-15 12:02:53.193 CST [323286] ERROR:  could not open shared memory segment "/PostgreSQL.2816709408": No such file or directory
Jun 15 12:03:53 fanyang-legion postgres[323334]: 2025-06-15 12:03:53.219 CST [323334] ERROR:  could not open shared memory segment "/PostgreSQL.2816709408": No such file or directory
Jun 15 12:04:53 fanyang-legion postgres[323385]: 2025-06-15 12:04:53.232 CST [323385] ERROR:  could not open shared memory segment "/PostgreSQL.2816709408": No such file or directory
Jun 15 12:05:04 fanyang-legion postgres[323386]: 2025-06-15 12:05:04.501 CST [323386] FATAL:  could not open shared memory segment "/PostgreSQL.2816709408": No such file or directory

解决方法:

PostgreSQL 11 Shared Memory Error: could not open shared memory segment "/PostgreSQL.XXXXXXXX": No such file or directory

# sudo vim /etc/systemd/logind.conf
RemoveIPC=no
systemctl restart systemd-logind.service

一键清理空的 Github Repo

在 GitHub 上创建了一堆 repository 但是又没空写,怎么把这些空的 repository 都删了呢?

写了一个小脚本 find-empty-github-repo 把他们都删了。

使用方法

  1. 点击这里创建一个 token,并且具有 repo 权限。

  2. 创建一个 .env 把 token 填进去,然后运行脚本。

详细的操作参考 README.md

vLLM 部署为 systemd 服务

配置 vLLM 环境,并且让他随着系统自启动

安装环境:

mkdir my-vllm
cd my-vllm

uv init
uv add vllm

编写 service 文件:

# vim /etc/systemd/system/vllm.service

[Unit]
Description=vLLM
After=network.target
Wants=network.target

[Service]
Type=simple
Environment=HF_ENDPOINT=https://hf-mirror.com
WorkingDirectory=/opt/vllm
ExecStart=uv run vllm serve "Qwen/Qwen3-Embedding-0.6B"
Restart=always
RestartSec=10
User=user
Group=user

[Install]
WantedBy=multi-user.target

vLLM,启动!

systemctl daemon-reload
systemctl enable --now vllm

默认端口

常用 Go modules

鄙人常用的一些 go mod,备查

存数据

  • github.com/cockroachdb/pebble
  • github.com/mattn/go-sqlite3
  • github.com/spf13/afero
  • github.com/syndtr/goleveldb
  • gorm.io/gorm
  • gorm.io/driver/sqlite

错误处理

  • github.com/cockroachdb/errors

哈希

  • github.com/cespare/xxhash

测试

  • github.com/negrel/assert
  • github.com/stretchr/testify

命令行

  • github.com/urfave/cli/v3
  • github.com/schollz/progressbar/v3
  • github.com/joho/godotenv

日志

  • github.com/rs/zerolog
  • github.com/fanyang89/pzlog
  • github.com/outrigdev/outrig

字符串

  • github.com/gobwas/glob

缓存

  • github.com/maypok86/otter

Oracle Linux Shell Script to Calculate Values Recommended Linux HugePages Configuration (Doc ID 401749.1)

Oracle Doc ID 401749.1 的脚本,自动配置 hugepage

#!/bin/bash
#
# hugepages_settings.sh
#
# Linux bash script to compute values for the
# recommended HugePages/HugeTLB configuration
# on Oracle Linux
#
# Note: This script does calculation for all shared memory
# segments available when the script is run, no matter it
# is an Oracle RDBMS shared memory segment or not.
#
# This script is provided by Doc ID 401749.1 from My Oracle Support
# http://support.oracle.com
# Welcome text
echo "
This script is provided by Doc ID 401749.1 from My Oracle Support
(http://support.oracle.com) where it is intended to compute values for
the recommended HugePages/HugeTLB configuration for the current shared
memory segments on Oracle Linux. Before proceeding with the execution please note following:
* For ASM instance, it needs to configure ASMM instead of AMM.
* The 'pga_aggregate_target' is outside the SGA and
 you should accommodate this while calculating the overall size.
* In case you changes the DB SGA size,
 as the new SGA will not fit in the previous HugePages configuration,
 it had better disable the whole HugePages,
 start the DB with new SGA size and run the script again.
And make sure that:
* Oracle Database instance(s) are up and running
* Oracle Database 11g Automatic Memory Management (AMM) is not setup
 (See Doc ID 749851.1)
* The shared memory segments can be listed by command:
 # ipcs -m
Press Enter to proceed..."
read
# Check for the kernel version
KERN=`uname -r | awk -F. '{ printf("%d.%d\n",$1,$2); }'`
# Find out the HugePage size
HPG_SZ=`grep Hugepagesize /proc/meminfo | awk '{print $2}'`
if [ -z "$HPG_SZ" ];then
 echo "The hugepages may not be supported in the system where the script is being
executed."
 exit 1
fi
# Initialize the counter
NUM_PG=0
# Cumulative number of pages required to handle the running shared memory segments
for SEG_BYTES in `ipcs -m | cut -c44-300 | awk '{print $1}' | grep "[0-9][0-9]*"`
do
 MIN_PG=`echo "$SEG_BYTES/($HPG_SZ*1024)" | bc -q`
 if [ $MIN_PG -gt 0 ]; then
 NUM_PG=`echo "$NUM_PG+$MIN_PG+1" | bc -q`
 fi
done
RES_BYTES=`echo "$NUM_PG * $HPG_SZ * 1024" | bc -q`
# An SGA less than 100MB does not make sense
# Bail out if that is the case
if [ $RES_BYTES -lt 100000000 ]; then
 echo "***********"
 echo "** ERROR **"
 echo "***********"
 echo "Sorry! There are not enough total of shared memory segments allocated for
HugePages configuration. HugePages can only be used for shared memory segments
that you can list by command:
 # ipcs -m
of a size that can match an Oracle Database SGA. Please make sure that:
* Oracle Database instance is up and running
* Oracle Database 11g Automatic Memory Management (AMM) is not configured"
 exit 1
fi
# Finish with results
case $KERN in
 '2.4') HUGETLB_POOL=`echo "$NUM_PG*$HPG_SZ/1024" | bc -q`;
 echo "Recommended setting: vm.hugetlb_pool = $HUGETLB_POOL" ;;
 '2.6') echo "Recommended setting: vm.nr_hugepages = $NUM_PG" ;;
 '3.8') echo "Recommended setting: vm.nr_hugepages = $NUM_PG" ;;
 '3.10') echo "Recommended setting: vm.nr_hugepages = $NUM_PG" ;;
 '4.1') echo "Recommended setting: vm.nr_hugepages = $NUM_PG" ;;
 '4.14') echo "Recommended setting: vm.nr_hugepages = $NUM_PG" ;;
 '4.18') echo "Recommended setting: vm.nr_hugepages = $NUM_PG" ;;
 '5.4') echo "Recommended setting: vm.nr_hugepages = $NUM_PG" ;;
 *) echo "Kernel version $KERN is not supported by this script (yet). Exiting." ;;
esac
# End